
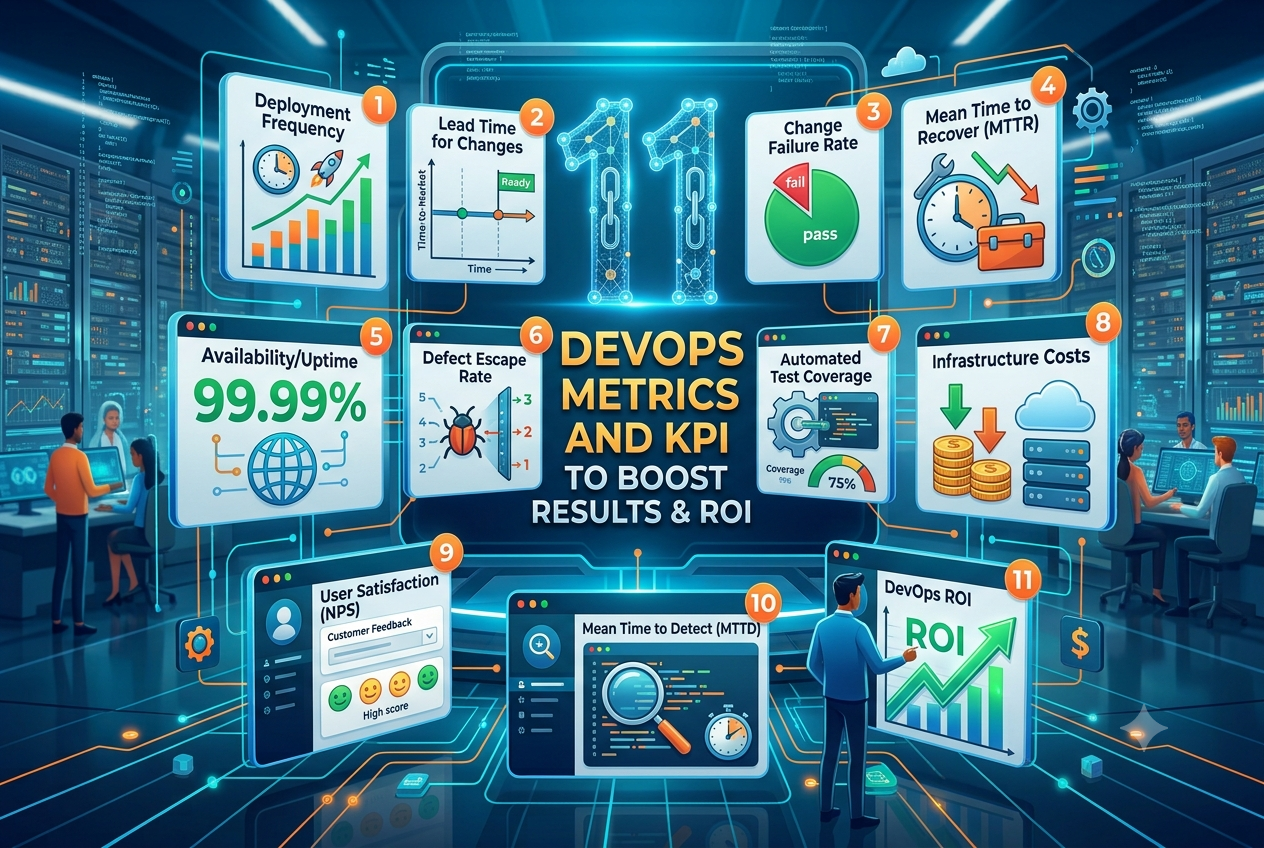
11 DevOps Metrics And KPI To Boost Results ROI
DevOps brings development and operations teams together to deliver software faster, more reliably, and with greater consistency. However, implementing DevOps practices alone does not guarantee better results. Organizations need measurable indicators to understand whether their processes are actually improving.
DevOps metrics and KPIs help teams evaluate software delivery speed, quality, stability, operational performance, and business outcomes. By tracking the right measurements, organizations can identify bottlenecks, improve workflows, reduce failures, and make better technology investments.
What Are DevOps Metrics and KPIs?
DevOps metrics are measurable indicators used to evaluate software development, deployment, and operational performance.
They can help teams answer questions such as:
How quickly are we delivering software?
How frequently are we deploying?
How often do deployments fail?
How quickly can we recover from failures?
Are production incidents decreasing?
Is automation improving productivity?
Are DevOps investments producing business value?
The goal is not to measure everything. Teams should focus on metrics that provide actionable information.
1. Deployment Frequency
Deployment frequency measures how often an organization successfully releases software to production.
A higher deployment frequency can indicate that teams are capable of delivering smaller changes consistently.
Tracking deployment frequency can help identify:
Release bottlenecks
Manual processes
Approval delays
Infrastructure limitations
Testing constraints
The metric should be considered alongside quality and stability rather than treated as an isolated target.
2. Lead Time for Changes
Lead time for changes measures the time required to move a code change from development into production.
A shorter lead time can indicate an efficient software delivery pipeline.
Teams can improve lead time by:
Automating builds
Automating testing
Improving code review workflows
Implementing CI/CD
Reducing manual approvals
Improving deployment processes
Reducing unnecessary delays can help organizations deliver business functionality faster.
3. Change Failure Rate
Change failure rate measures the percentage of deployments that result in production failures, rollbacks, or remediation work.
A high change failure rate may indicate problems with:
Testing
Code quality
Deployment processes
Infrastructure configuration
Release planning
Monitoring this metric helps teams balance delivery speed with software stability.
4. Mean Time to Recovery
Mean Time to Recovery (MTTR) measures how quickly a team can restore service after a production incident.
A lower MTTR generally indicates that teams can identify and resolve operational problems efficiently.
Organizations can improve recovery time through:
Automated monitoring
Centralized logging
Incident response procedures
Automated rollback
Infrastructure automation
Clear ownership
Fast recovery helps reduce downtime and its potential business impact.
5. Mean Time to Failure
Mean Time to Failure measures the average operating time between failures.
Monitoring this metric can provide insight into system reliability and stability.
Teams can improve reliability through:
Better testing
Infrastructure monitoring
Preventive maintenance
Automated deployments
Performance optimization
Proactive incident management
6. Defect Escape Rate
Defect escape rate measures the number or percentage of defects that reach production instead of being detected during development and testing.
A high defect escape rate may indicate weaknesses in:
Test coverage
Quality assurance
Code review
Automated testing
Release validation
Tracking escaped defects can help QA and development teams identify opportunities to strengthen the software delivery lifecycle.
7. Pipeline Success Rate
A CI/CD pipeline should provide consistent and reliable software delivery.
Pipeline success rate measures how frequently builds, tests, and deployments complete successfully.
Teams can monitor:
Build failures
Test failures
Deployment failures
Pipeline duration
Infrastructure-related failures
Improving pipeline reliability reduces unnecessary interruptions to development teams.
8. Test Automation Coverage
Test automation coverage indicates how much of the application's testing process is automated.
Automation can help reduce repetitive manual testing and provide faster feedback to developers.
Useful areas for automation include:
Unit testing
API testing
Integration testing
Regression testing
UI testing
Security testing
Automation should focus on meaningful test scenarios rather than simply maximizing the percentage of automated tests.
9. Infrastructure Utilization
Infrastructure utilization measures how effectively computing resources are being used.
Depending on the environment, teams may monitor:
CPU usage
Memory usage
Storage
Network utilization
Container utilization
Cloud resource usage
Monitoring infrastructure helps organizations identify underutilized resources and potential capacity problems.
It can also contribute to better cloud cost management.
10. Application Availability
Application availability measures the percentage of time a service remains operational and accessible.
High availability is particularly important for applications that support critical business processes.
Teams can improve availability through:
Redundant infrastructure
Load balancing
Automated monitoring
Failover mechanisms
Disaster recovery planning
Proactive maintenance
Availability metrics should be aligned with the service-level expectations of the application.
11. DevOps ROI
DevOps initiatives ultimately need to create business value.
DevOps ROI can be evaluated by comparing investments in people, tools, infrastructure, and automation with measurable improvements such as:
Reduced deployment costs
Lower downtime
Faster delivery
Reduced defect remediation
Improved developer productivity
Lower infrastructure costs
Increased customer satisfaction
ROI should not be measured solely by engineering metrics. Business outcomes are equally important.
How to Use DevOps KPIs Effectively
Collecting metrics is only the beginning. Teams need to use the information to improve processes.
Establish a Baseline
Measure current performance before introducing major changes. This gives teams a reference point for evaluating improvement.
Track Trends
A single measurement rarely provides enough information. Monitoring trends over time can reveal whether processes are improving or deteriorating.
Connect Metrics to Business Goals
Technical metrics should support broader business objectives such as faster product delivery, improved reliability, reduced costs, and better customer experience.
Avoid Measuring for the Sake of Measurement
Too many metrics can create unnecessary reporting overhead. Select KPIs that provide actionable insights.
Review Metrics Regularly
DevOps teams should periodically review their KPIs and adjust them as products, teams, infrastructure, and business priorities change.
Benefits of Tracking DevOps Metrics
A structured DevOps measurement strategy can help organizations:
Improve software delivery speed
Reduce deployment failures
Increase system reliability
Identify operational bottlenecks
Improve testing efficiency
Reduce downtime
Optimize infrastructure costs
Increase development productivity
Improve customer experience
Understand technology ROI
Conclusion
DevOps metrics and KPIs provide organizations with a practical way to understand the effectiveness of their software delivery and operational processes.
Metrics such as deployment frequency, lead time for changes, change failure rate, MTTR, defect escape rate, pipeline success rate, test automation coverage, infrastructure utilization, availability, and ROI can provide valuable insight when tracked in the right context.
The objective should not simply be to improve individual numbers. Instead, organizations should use DevOps metrics to identify bottlenecks, improve collaboration, strengthen software quality, increase reliability, and connect engineering performance with measurable business outcomes.